Data Centers & Cloud
The buildout behind the AI bill
Hyperscaler capex, colocation supply, power, cooling and networking — where the money goes after the GPU order, and which companies book it.
2026-08-26

2026-08-25
The AI data-center buildout’s schedule risk is shifting from permits to field capacity—and it changes who prints margin
As AI megawatt demand accelerates, the bottleneck is increasingly the “build the building” layer: general contractor throughput and the MEP electrical/mechanical labor pool that physically delivers power and cooling. For listed contractors and engineering-services firms, that translates into a different margin map than the chip stack: working-capital intensity and execution reliability start to matter more than design throughput alone.
SpaceX’s $100B “Starbase, Louisiana” reframes AI from power-and-chips to launch-and-orbit capacity
SpaceX’s planned $100B Starbase, Louisiana spaceport targets propellant production, vehicle processing, and an expanded launch cadence—then it explicitly pulls forward the timeline for orbital AI data-center deployments to late 2027. The market implication is simple: when orbital compute moves from prototype flights to scaled constellations, launch slots become a gating input that can reprice the space/value chain.
Subsea cable capacity is turning into the “sovereignty toll” for AI inference—because landing stations now face national-security scrutiny
AI traffic is increasingly priced not just by how much fiber exists, but by who can access it at landing stations and on their terrestrial handoff path. A June 4, 2026 FCC order tightens and accelerates national-security oversight around cable landing station equipment, SLTE access reporting, and circuit capacity compliance—raising the cost and friction of cross-border inference paths.
2026-08-24
2026-08-23
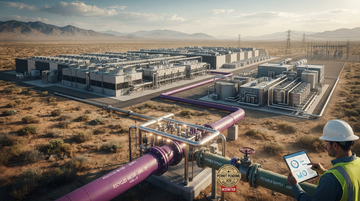
AI Data Centers Are Entering a “Second Constraint” Era—Water Permits, Not Just Power, Decide Who Can Scale
Water scarcity and permitting are moving from background risk to a primary scheduling constraint for AI data centers in drought-prone regions. The practical battleground is cooling choice (water-withdrawing vs. closed-loop) and whether hyperscalers can route cooling demand through recycled-water systems—shifting capex from plant construction into treatment, monitoring, and recycling infrastructure.
AI fabrics hit the “fabric wall”: switch-ASIC + SerDes/retimer capacity, not GPU supply, is tightening the next data-center upgrade cycle
As AI clusters scale toward higher-port-count, 800G-class and 1.6T-era fabrics, the limiting factor is shifting from GPU compute availability to the networking fabric bill of materials—especially switch-ASIC throughput and the SerDes/retimer ecosystems that make optical and copper links behave at scale. Arista has already disclosed that component shortages and lead-time dynamics force it to use non-cancellable semiconductor purchase commitments that can raise working-capital needs and pressure gross margins, while its 1.6T-ready 7060XE7 line shows the engineering push toward the next fabric tier. The practical investor takeaway: watch the silicon and interface bottlenecks that sit between “GPU arrival” and “fully networked training,” because that’s where revenue timing and margins can swing first.
AI server build-out is paying ODMs with single-digit margins — the market sees GPU demand, but not the margin math between silicon and racks
AI server demand is booming, yet the ODM layer that converts GPU shipments into hyperscaler-usable racks is structurally capped by cost-of-sales pass-through, tariffs, expedite charges, and component sourcing concentration. Using Supermicro’s latest SEC disclosure as a load-bearing reference point for gross margin drivers, and cross-checking the revenue scale of major ODMs like Hon Hai Precision, Quanta Computer, and Wistron, the payoff is less “margin expansion” than “volume absorption,” which changes how investors should price order growth and onshoring headlines.
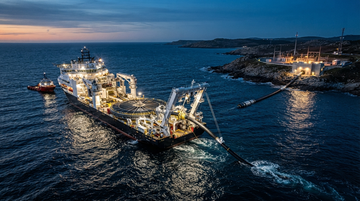
The AI transatlantic build-out is bumping into a real-world bottleneck: cable installation ships and landing capacity
Hyperscalers’ AI demand is translating into a longer “time-to-connect” problem: subsea cable capacity is not just manufactured, it must also be installed with a limited fleet of specialized ships and then terminated at cable landing stations. Prysmian’s planned €350M investment to expand its cable-laying fleet to eight vessels by adding new deep- and shallow-water assets underlines how installation capacity is becoming the choke point—one that can delay AI traffic rollouts even when fiber and systems are ready.
2026-08-22
PJM congestion hit $6B in six months—AI load growth is turning transmission limits into a recurring, priced toll
PJM’s transmission congestion costs jumped 43% to $6B in the first half of 2026, driven by binding high-voltage constraints and overload periods. The market implication isn’t just “more congestion”: it’s a shift in who effectively pays for expansion—ratepayers via settlement and capacity economics—while also tightening the demand signal for transformers and high-voltage equipment.
Ubiquiti: Q4’s “AI-edge” signal lives in margins and inventory, not sales
In Ubiquiti’s fiscal Q4, revenue rose to $937.3M, but the stock’s real battleground is gross margin and working-capital behavior. FY2026 ended with $780.4M of inventory and $928.7M operating cash flow, making the upgrade-cycle question hinge on whether inventory is converting into margin and cash again.
2026-08-21
2026-08-20
The CFTC’s Compute-Derivatives Opening Turns GPU Capacity Into a Hedgeable “Pricing Primitive”
The CFTC’s Aug. 19, 2026 request for comment is the first real regulatory nudge toward compute futures—contracts whose value tracks AI computing capacity costs. If compute pricing becomes tradable, it can let hyperscalers, data-center operators, and market makers shift utilization risk from long-dated capex into hedgeable cash flows—changing how investors price the AI buildout.
Marvell just got a Google route into TPU-attached custom AI silicon—tightening the “ASIC duopoly” pressure on NVIDIA’s inference economics
Marvell’s newly disclosed agreement with Google ties Marvell-designed custom semiconductor products to the TPU ecosystem, with Google receiving a warrant equivalent to about $12.2B of Marvell shares and vesting linked to Custom Products revenue. The investment implication is not “Marvell wins a chip”; it is that hyperscalers can diversify beyond Broadcom-led custom designs while still optimizing inference compute near TPU—raising the probability of faster cost-per-inference improvements that directly pressure NVIDIA’s accelerator pricing power.
TerraPower’s Natrium turns nuclear into a data-center “load-following battery,” not just baseload
Natrium pairs a 345 MWe sodium fast reactor with a molten-salt energy storage system that can boost output to 500 MWe, giving nuclear dispatchability that hyperscalers need for AI-driven peak demand. TerraPower is already moving Kemmerer Unit 1 through the 10 CFR Part 50 construction-permit milestone and building a HALEU fuel path—suggesting the next bottleneck is less “baseload availability” and more flexible, contractable output.
2026-08-19
Pennsylvania turns AI data-center approvals into a consent-gated process—ending the “buy gas rights” shortcut and reshuffling who can finance fast buildouts
Pennsylvania’s Aug. 18, 2026 executive order makes AI data-center permitting in the state conditional on executing enforceable GRID commitments and proving local approvals for projects above 25 MW. The change directly challenges the economics of “permit-by-power-queue bypass” strategies, where developers secured fuel rights while waiting behind grid and permitting constraints.
Velaura AI’s $110M Series A reframes the AI power bottleneck as an “inside-the-silicon” battleground
Velaura AI raised $110M in a Series A and says its Titan Core silicon design can enable up to 2x lower chip power (up to ~500W savings vs a typical 1000W GPU/XPU) and cut math energy 2–4x. If hyperscalers scale this as a licensing layer, it could compress “compute-per-rack” economics and shift budgeting from just grid and cooling toward silicon efficiency—pressuring incumbent custom-silicon economics while benefiting thermal/power infrastructure winners.
2026-08-18
2026-08-17
The real AI “tolls the rack” war: Ethernet-scale NVLink’s moat can’t stop fabric spend from compounding
At 100k-GPU scales, the winning network design is less about peak interconnect bandwidth and more about how fast hyperscalers can buy, deploy, and oversubscribe the fabric without sacrificing collective efficiency. The Ethernet side is gaining momentum through purpose-built standards like Ultra Ethernet, while NVLink remains the scale-up “in-rack” fast path—so the interconnect profit pool migrates between chip, switch, and server layers depending on where architectures settle.
The 48V rack bus is the new price bottleneck in AI data centers—SiC/GaN power silicon may capture the “dollars-per-watt” upside that electrical OEMs can’t
As AI racks scale toward hundreds of kilowatts, the in-rack power-delivery chain (PSU → 48V bus → VRMs → SiC/GaN switching) is getting harder to build, cool, and qualify as one stack. Primary disclosures show that the Vera Rubin NVL72 rack design already concentrates power demand into multiple 110kW shelves, while grid-side electrical backlogs (Eaton) and 800V HVDC guidance (onsemi) point to a multi-year build-out. Investors should expect silicon vendors supplying SiC/GaN efficiency and density to monetize the “per-watt” upgrade cycle faster than the grid/electrical OEM layer.
What to expect
Evidence-first notes with a visible point of view.
This section collects sharp takes on earnings, shareholder meetings, and market structure. Each new piece should make the thesis, the facts, and the implications obvious within the first few screens.
Expect direct analysis, not generic commentary.
Expect the data to be explicit and the argument to be easy to follow.